LLM Quantization Explained: How 4-Bit and 8-Bit Models Cut Memory Costs
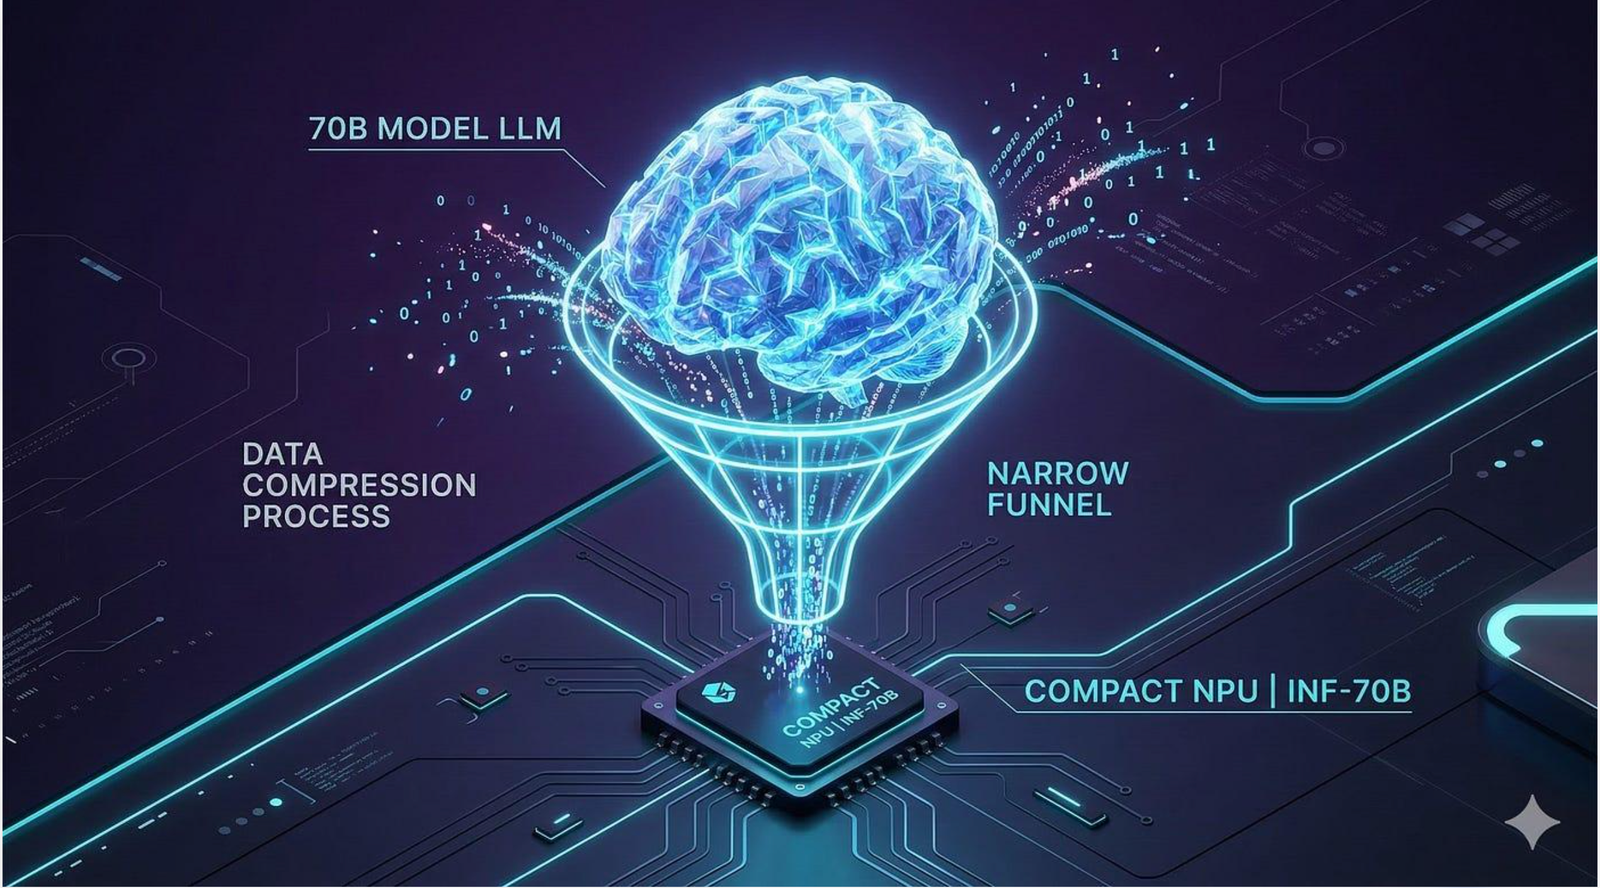
Large language models are often limited not only by how much compute they need, but by how much memory their weights occupy. A model that performs well on a data-centre GPU may be difficult to run on a workstation, laptop or smaller cloud instance. Quantization helps close that gap by representing model values with fewer bits.
That is why model repositories and local-inference tools offer labels such as 8-bit, 4-bit, Q4_K_M and Q8_0. These labels describe different ways of storing numerical values more compactly. They can make models easier to deploy, but they do not make the trade-offs disappear: lower precision can affect output quality, speed, hardware compatibility and memory use in different ways.
This guide explains what LLM quantization does, how 4-bit and 8-bit approaches compare, where formats such as GGUF and libraries such as bitsandbytes fit, and how to choose a model based on measurements rather than a filename.
What is LLM quantization?
Neural networks contain large collections of learned numerical parameters called weights. During training and inference, these values are commonly represented using formats such as 32-bit floating point (FP32), 16-bit floating point (FP16), or brain floating point (BF16). Each value occupies a certain number of bits in memory.
Quantization maps values from a higher-precision representation into a smaller set of representable values. Instead of storing every weight in a 16-bit format, a quantized model may store many weights using 8 bits or 4 bits, alongside scaling factors, metadata or other information needed to interpret them.
A simplified uniform quantization scheme can be written as:
q = round(x / scale) + zero_point
Here, x is the original value, scale controls the step size, and zero_point shifts the integer range. Real LLM quantization methods can be more sophisticated: they may use non-uniform codebooks, per-channel or per-group scales, special handling for outliers, or mixed precision for sensitive components.
The key idea is straightforward: use fewer bits to represent most values, while managing the numerical error introduced by compression.
Why quantization matters for LLM deployment
Model weights must be available to the inference engine while the model generates text. If the weights do not fit in available GPU memory, the system may need to use multiple GPUs, move data between CPU and GPU, or run parts of the model on system RAM. These choices can increase complexity and affect latency.
Quantization can help in several ways:
- Lower weight memory: Smaller representations reduce the space required to store model parameters.
- More deployment options: A model that once required a larger accelerator may become practical on a smaller device, depending on runtime overhead and workload.
- Potentially better throughput: Some hardware and kernels process low-precision operations efficiently, although smaller files do not automatically mean faster generation.
- Lower infrastructure pressure: Fitting more model instances or larger batches into a fixed memory budget can improve serving economics.
- Local experimentation: Quantized checkpoints make it easier to test open-weight models on personal workstations and edge systems.
Quantization is one part of the inference-efficiency story. It complements serving architecture, batching, caching and networking rather than replacing them. See our article The Next AI Bottleneck Isn’t the Model — It’s Inference for a broader look at runtime performance.
4-bit vs 8-bit: what changes?
The bit count describes the precision used for a quantized representation, not necessarily the exact average size of every model component. As a rough illustration, consider a model with 7 billion parameters. If every parameter were stored at exactly 16 bits, the raw weight data would require about 14 billion bytes, or roughly 14 GB in decimal units. At 8 bits, the simple raw-weight estimate is about 7 GB; at 4 bits, about 3.5 GB.
These are estimates, not the full memory requirement. Quantization scales, unquantized layers, embeddings, temporary buffers, runtime overhead and the key-value (KV) cache add to the total. Actual checkpoint sizes and runtime memory vary by architecture and quantization format.
RepresentationRaw weight estimate for 7B parametersTypical consideration FP16 / BF16About 14 GBHigher precision; larger memory footprint 8-bitAbout 7 GBOften a conservative compression choice 4-bitAbout 3.5 GBMuch smaller weights; quality and format need testing
8-bit quantization
Eight-bit quantization reduces the number of bits used for many weights while retaining more representational detail than a 4-bit scheme. It can be a useful starting point when memory is constrained but the application is sensitive to quality changes.
Hugging Face's bitsandbytes integration includes LLM.int8(), which uses an approach designed to handle outlier features more carefully than a naive conversion of every value to an 8-bit integer. The documentation describes separating outliers for higher-precision computation while processing the remaining values in 8-bit form. This is a reminder that practical quantization is not always a simple uniform cast.
4-bit quantization
Four-bit methods compress weights further. One well-known option in the bitsandbytes ecosystem is NormalFloat4 (NF4), introduced in the QLoRA work and designed for weight distributions that are approximately normal. Hugging Face documents NF4 as a recommended choice for training 4-bit base models with QLoRA.
Four-bit does not mean every part of the model and inference process uses four bits. Compute may use FP16 or BF16, and some layers or tensors may remain at higher precision. The exact configuration matters.
How much memory does a quantized model really need?
A useful first estimate is:
Raw weight memory ≈ parameter count × bits per parameter ÷ 8
For a 7-billion-parameter model at 4 bits, that gives approximately 3.5 billion bytes before overhead. For a 13-billion-parameter model, the corresponding raw estimate is about 6.5 GB. These calculations help compare formats, but they are not reliable hardware-sizing guarantees.
During inference, memory is also used by the KV cache, which stores attention keys and values for the active context. Its size depends on model architecture, number of layers, attention heads, context length, batch size and cache data type. Long prompts and concurrent requests can therefore push memory use far above the weight-only estimate.
Before selecting a GPU, measure the actual model under the intended context length and concurrency. Leave headroom for runtime allocations and operating-system needs rather than planning to use every available byte.
Popular quantization ecosystems and formats
bitsandbytes with Transformers
The bitsandbytes library integrates with Hugging Face Transformers to load models in 8-bit or 4-bit modes. It is commonly used for memory-efficient inference and for QLoRA workflows, where a quantized base model is combined with trainable low-rank adapter weights.
A simplified 4-bit loading example looks like this:
import torch
from transformers import AutoModelForCausalLM, BitsAndBytesConfig quant_config = BitsAndBytesConfig( load_in_4bit=True, bnb_4bit_quant_type="nf4", bnb_4bit_compute_dtype=torch.bfloat16, bnb_4bit_use_double_quant=True,
) model = AutoModelForCausalLM.from_pretrained( "your-model-id", device_map="auto", quantization_config=quant_config,
)
This is an illustrative configuration, not a universal recipe. Replace the model identifier with a model you are licensed and equipped to use, and check the current library documentation for hardware and version requirements. The compute data type and device placement should match the target hardware.
GGUF and llama.cpp
GGUF is a model file format used by the llama.cpp ecosystem. It can store model tensors and metadata in a form designed for efficient loading across supported backends. GGUF files often include quantization labels such as Q4_K_M and Q8_0.
Those labels are not interchangeable with every other library's “4-bit” or “8-bit” setting. GGUF quantization types can use block-wise schemes and mixed tensor choices, so the effective bits per weight and quality characteristics vary. The llama.cpp project publishes quantization options and example measurements in its source and documentation; users should check the exact model and runtime combination they plan to deploy.
GPTQ and AWQ
GPTQ and AWQ are other prominent approaches to post-training weight quantization. They use calibration data and quantization-aware procedures to reduce the impact of rounding error. AWQ, for example, uses activation information to identify salient weights and protect them through scaling. The best choice depends on supported kernels, model architecture, hardware and evaluation results—not just the algorithm's name.
Does quantization reduce model quality?
It can. Quantization introduces approximation error, and aggressive compression can affect some model behaviors more than others. A model may retain fluent everyday conversation while showing weaker performance on precise reasoning, code generation, multilingual tasks or domain-specific questions.
There is no single quality-loss number that applies to every model. Results depend on the original checkpoint, quantization method, calibration data, bit width, group size, inference implementation and evaluation task. A benchmark score from one model family should not be assumed to predict another model's behavior.
It is also possible for a quantized model to run faster on one device and slower on another. If a GPU lacks efficient support for a particular low-bit format, conversion or dequantization overhead can offset memory savings. CPU, GPU and integrated-memory systems may behave differently.
How to choose between 4-bit and 8-bit
Start with the constraints of the application rather than choosing the smallest checkpoint available.
- Choose 8-bit as a baseline when you need a substantial memory reduction and want to preserve more numerical detail, subject to validation.
- Test 4-bit when memory is the main constraint or when fitting the model locally is more important than retaining the maximum possible precision.
- Compare multiple formats if your runtime supports them. A well-calibrated 4-bit format may outperform a less suitable alternative at a similar file size.
- Consider context and concurrency before buying hardware. Weight memory is only one part of serving memory.
- Check licenses and provenance for the base model and any redistributed quantized checkpoint. Quantization does not change the model's usage license.
A practical benchmark checklist
Before deploying a quantized model, compare it with the original checkpoint using the same prompts, decoding settings, context length and runtime conditions. A useful evaluation includes:
- Task quality: Test representative prompts for the real application, including difficult and edge cases.
- Factual reliability: Check whether compression changes hallucination rates or the model's willingness to express uncertainty.
- Code and reasoning: Run task-specific tests if the model will generate code, follow multi-step instructions or perform structured analysis.
- Latency and throughput: Measure time to first token, generation speed and requests per second at realistic batch sizes.
- Peak memory: Record GPU and system RAM use at the longest expected context and concurrency.
- Operational stability: Test long sessions, cancellation, batching, model reloads and fallback behavior.
Keep the original model as a baseline and document the exact checkpoint, quantization type, runtime version, hardware and evaluation set. This makes results reproducible and helps teams detect regressions after upgrades.
Quantization is one part of an efficient AI stack
Smaller weights can make a model easier to host, but production inference also depends on request routing, batching, caching, context management, observability and failure handling. A quantized model that fits on one GPU may still be a poor choice if it produces unacceptable answers or cannot meet latency targets.
For a wider view of these engineering trade-offs, read our guides on inference as the next AI bottleneck, local LLMs and data security, and measuring the cost of AI workflows.
Conclusion
LLM quantization reduces the memory needed for model weights by representing numerical values with fewer bits. Eight-bit formats often offer a useful balance between compression and precision, while four-bit formats can make larger models practical on more limited hardware. Neither format guarantees a particular speed, quality level or total memory requirement.
The right quantized model is the one that meets your application's quality, latency, memory and cost requirements under realistic tests. Start with a baseline, compare supported formats, measure the complete inference workload and keep a rollback path. That turns quantization from a file-size shortcut into a sound deployment decision.
Further reading and official documentation
- Hugging Face Transformers: bitsandbytes quantization
- Hugging Face PEFT: quantization and QLoRA
- llama.cpp project and quantization tooling
- QLoRA: Efficient Finetuning of Quantized LLMs
- AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration
- GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers
Comments
0To comment, choose whether you want to register or continue as a guest.