The Next AI Bottleneck Isn’t the Model — It’s Inference
September 29, 2026
The AI industry has spent years optimizing the race to build larger and more capable models. But as those models move into products, robots, cybersecurity systems and other real-world workloads, another constraint is becoming harder to ignore: inference.
Inference is the moment an AI system actually does work for a user or another machine. It turns a trained model into a response, a recommendation, a code change, a robot action or a decision. And the economics and engineering of that moment are increasingly becoming a defining part of AI system design.
Recent developments point to the same direction from different angles. Cerebras has agreed to supply AI systems for cloud provider Gimlet Labs, with the deployment aimed particularly at high-performance inference. Microsoft Research has also published experiments showing that moving inference away from a robot and onto edge or cloud GPUs can improve performance, battery life and cost.
Training gets the headlines. Inference pays the bills.
Training creates a model, but inference is what happens every time that model is used.
That distinction matters because a production AI application may execute millions or billions of inference operations. A system that looks inexpensive during a prototype can become much more expensive when usage scales, especially if every request requires a large model, long context, multiple tool calls or repeated reasoning.
Inference also has a latency problem. A model can be highly capable in a benchmark and still feel poor in a product if users wait too long for an answer or a physical system cannot react quickly enough.
Why bigger models change the runtime equation
More capable models generally require more compute, memory and bandwidth. The challenge is not simply buying more GPUs. Engineers have to decide where computation should happen, which model should handle each task, how much context should be supplied and how requests should be scheduled.
For cloud AI, this creates a systems problem involving accelerators, networking, batching, caching and model serving. For edge devices, there is an additional constraint: power and physical space.
The result is a shift in architecture. Instead of assuming that every device should run the complete model locally, systems can distribute inference across the device, an edge server and centralized cloud infrastructure.
Robotics is exposing the problem early
Microsoft Research recently studied inference for mobile robotic manipulation and challenged the assumption that physical AI should rely primarily on onboard GPU computation.
In its experiments, Microsoft reported that some smaller GPUs could not accommodate the full workload. On capable but lighter hardware, mapping and planning could slow substantially compared with an A100, while navigation performance and model accuracy could also fall. The researchers found that offloading inference to more powerful edge or cloud GPUs improved response time and task performance.
There was another constraint: battery life. The research found that replacing a power-hungry onboard GPU with lighter hardware while sending inference to remote compute could substantially extend operating time.
That does not mean cloud inference is automatically better. Robots still have to deal with network latency, bandwidth, intermittent connectivity and the consequences of losing access to remote compute. The important point is architectural: physical AI may need inference to be distributed rather than tied to one piece of hardware.
The rise of inference-first hardware
The commercial market is responding to the same pressure.
On September 28, Cerebras announced a partnership with Gimlet Labs to supply CS-4 systems for the company’s AI cloud. Reuters reported that the systems are intended to support high-performance inference and that the planned deployment represents roughly 100 megawatts of power capacity.
The significance is broader than one hardware deal. AI infrastructure is increasingly being designed around the question of how quickly and efficiently models can serve real workloads, not only how fast they can be trained.
That opens room for specialized architectures. Different workloads may value throughput, latency, memory capacity, energy efficiency or predictable performance differently. There is unlikely to be one ideal inference processor for every application.
Three layers of the future inference stack
1. Model selection
Not every request needs the largest available model. Production systems can route simple tasks to smaller models and reserve expensive reasoning for cases that justify it. This turns model routing into a runtime optimization problem.
2. Compute placement
Inference can happen on a phone, PC, vehicle, robot, local server, edge facility or hyperscale cloud. The right location depends on latency, privacy, available compute, bandwidth and energy constraints.
3. Serving efficiency
Even after choosing a model and location, serving infrastructure matters. Batching, caching, memory management, quantization, scheduling and specialized accelerators can determine how much useful work a system gets from its hardware.
Why inference changes AI product design
When inference becomes a first-class engineering concern, AI products start looking different.
Developers have to measure more than model accuracy. They need metrics such as time to first token, end-to-end latency, tokens per second, cost per successful task, energy consumption and failure recovery. For agents, the calculation becomes even more complex because one user request may trigger several model calls and tool executions.
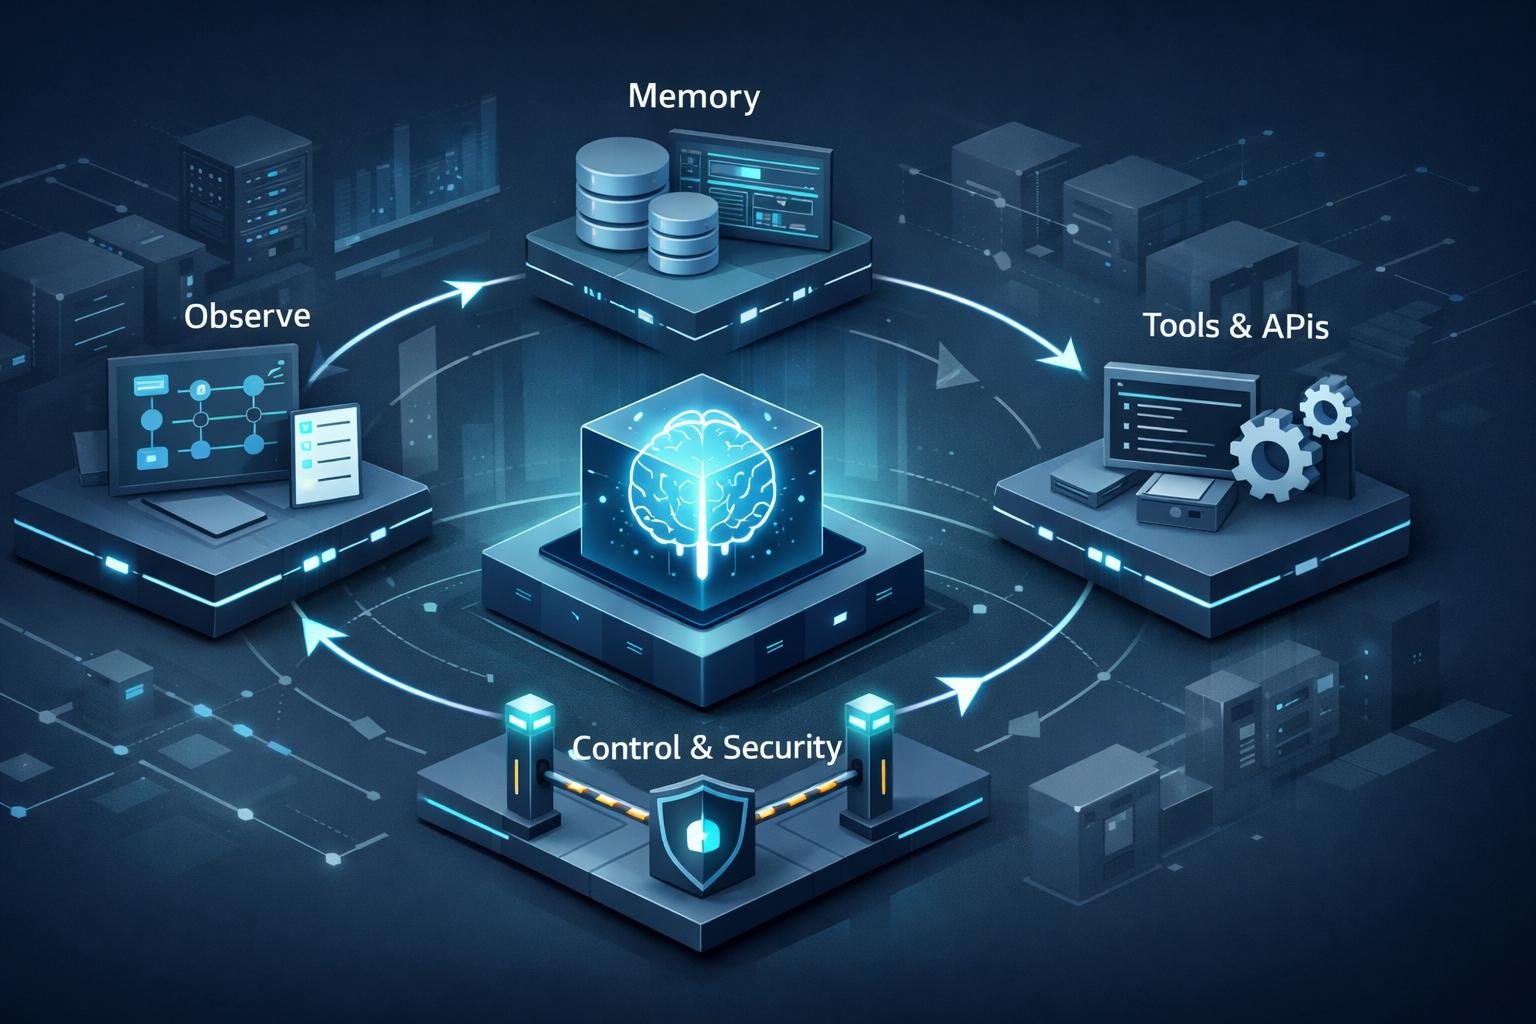
This also changes the definition of an AI platform. A strong platform is not simply a gateway to a model. It is a system for deciding which intelligence to use, where to run it, how much compute to spend and when to stop.
What to watch next
- Inference-specific chips: More hardware vendors will compete on latency, throughput and energy efficiency rather than training performance alone.
- Edge-cloud orchestration: Systems will increasingly split inference across local, edge and cloud resources.
- Dynamic model routing: Applications will choose models based on task difficulty, latency targets and cost budgets.
- Inference economics: AI businesses will need to understand cost per useful outcome, not just cost per token.
- Physical AI: Robotics and autonomous systems will make latency, connectivity and energy constraints impossible to ignore.
The bigger shift
The next stage of AI infrastructure may be defined less by the size of the model and more by the quality of the system serving it.
Training will remain enormously important. But once intelligence becomes a commodity that many products can access, the differentiator can move downstream: efficient inference, smart routing, reliable serving and the ability to put computation in the right place at the right time.
In other words, the AI race is moving from “Can we build a smarter model?” toward a harder production question: “Can we deliver that intelligence fast enough, cheaply enough and reliably enough to be useful?”
Sources
Microsoft Research, Offloaded inference for real-world physical AI robotics, September 23, 2026.
Reuters, Cerebras to supply AI systems to cloud computing startup Gimlet Labs, September 28, 2026.
Microsoft Research, LLM-42: Enabling Determinism in LLM Inference with Verified Speculation, September 2026.
Comments
0To comment, choose whether you want to register or continue as a guest.