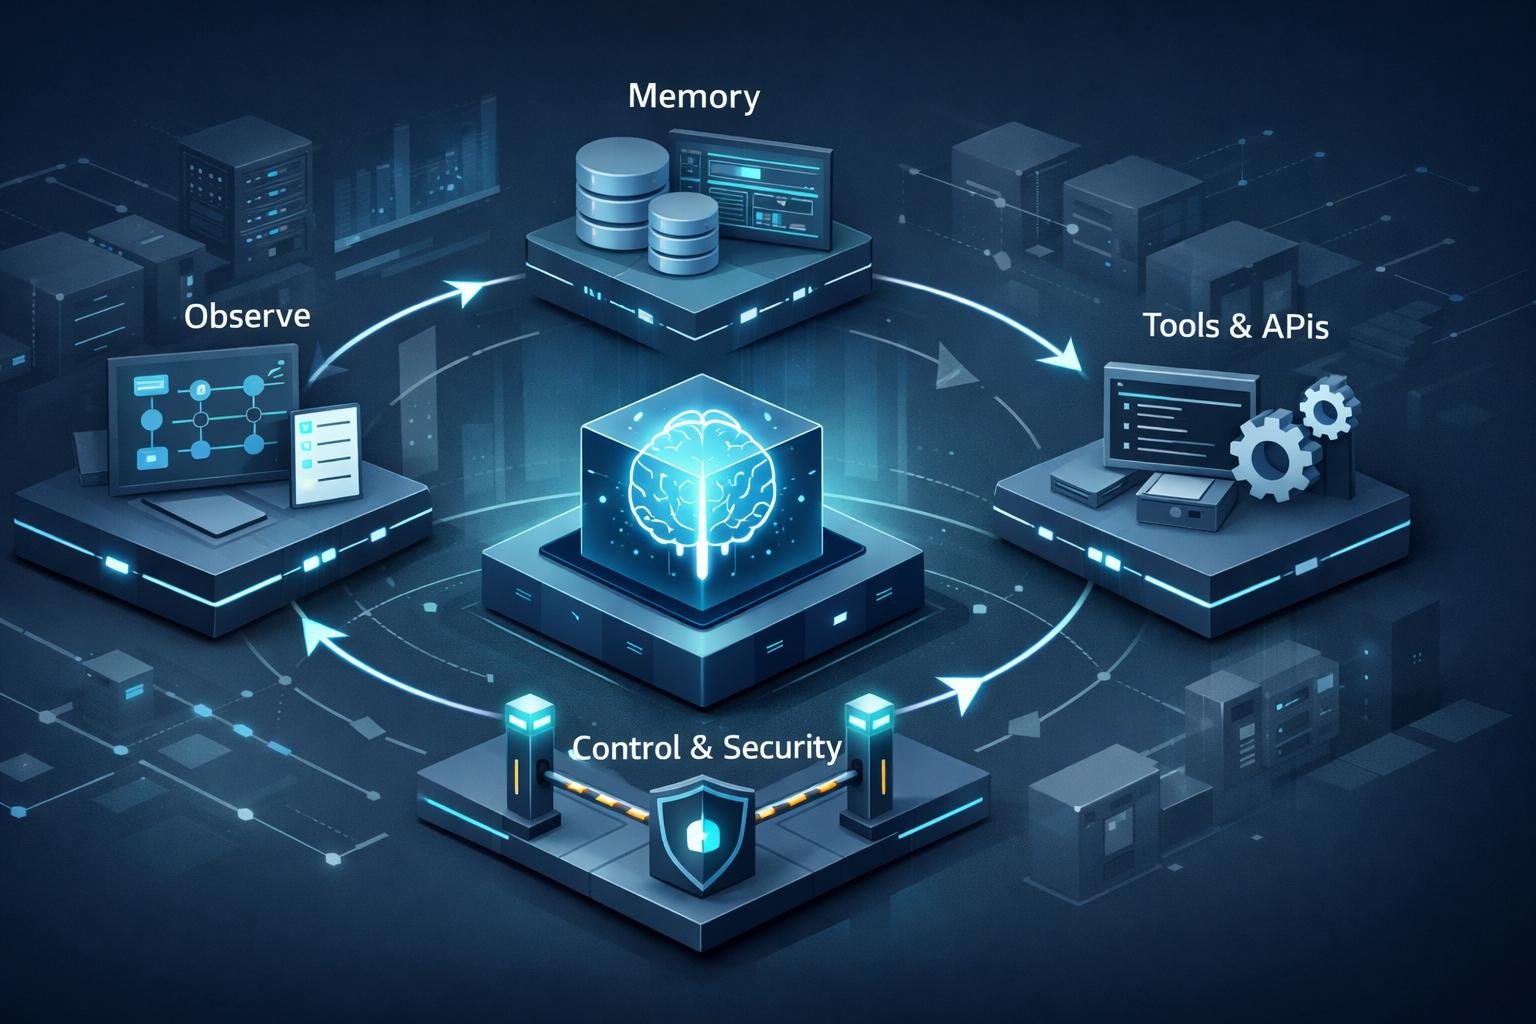
AI demos usually show the happy path: a user asks a question, the model responds, and the workflow finishes. Production systems live in a different world. Providers time out, rate limits appear, retrieval returns stale documents, tool calls fail, and model outputs can be incomplete or invalid.
The architectural question is not whether an AI component will fail. It is what the application does when it does. Graceful degradation means preserving as much useful, safe functionality as possible when one part of an AI system becomes unavailable or unreliable.
This is a different goal from making a model more capable. It is a system-design discipline: isolate failure domains, define fallback behavior, bound retries, and make uncertainty visible.
1. Treat the model as a dependency, not the application
A common design mistake is to put the model call directly in the critical path of every user action. If the model is slow or unavailable, the whole product appears broken—even when much of the requested work could still be completed deterministically.
Instead, separate the application into explicit layers:
- Product/API layer: validates requests, authenticates users and returns stable response contracts.
- Orchestration layer: decides which model, retrieval source or tool is needed for a task.
- AI services: model inference, embeddings, reranking and other probabilistic operations.
- Data and tool layer: databases, search indexes and external APIs, each with its own timeout and permission boundary.
- Policy and observability layer: enforces limits and records outcomes across the request lifecycle.
This separation makes it possible to degrade one capability without taking down the entire application.
2. Define fallbacks before you need them
A fallback should preserve the user’s goal, not merely return a different model response. The right behavior depends on the task and the consequences of being wrong.
Example: an internal knowledge assistant
Suppose an employee asks, “What is our current travel reimbursement limit?” The normal path retrieves policy documents, reranks passages, and asks a model to produce an answer with citations.
If the model provider times out, the system could show the matching policy passages and their dates instead of inventing an answer. If retrieval is unavailable, it could explain that it cannot verify the current policy and link to the canonical policy repository. If the documents are stale, it should disclose their date rather than presenting them as current.
That is graceful degradation: the experience becomes less convenient, but it remains honest and useful.
3. Use bounded retries, timeouts and circuit breakers
Retries can help with transient errors, but unlimited retries turn a small outage into a larger one. Set a deadline for the whole request, assign smaller timeouts to individual dependencies, and cap retries with backoff and jitter.
A circuit breaker can temporarily stop calls to a dependency that is repeatedly failing. While it is open, the application uses an approved fallback or returns a controlled error. Probe the dependency periodically and restore traffic gradually when it recovers.
Be careful with automatic retries on actions that change state. A timed-out payment, ticket creation or infrastructure operation may have succeeded even if the response was lost. Use idempotency keys, operation status checks, or explicit reconciliation rather than blindly repeating the action.
4. Route by task and risk—not just by model price
Model routing can improve resilience, but a second model is not automatically a safe fallback. Different models may have different context limits, tool support, data-handling terms and output reliability.
Define routing rules around the task:
- Use a deterministic function for calculations and validation whenever possible.
- Use a smaller or alternate model for low-risk summarization if it meets your quality threshold.
- Require stronger validation or human review for high-impact decisions and irreversible actions.
- Fail closed when a required security or policy check cannot run.
Keep a tested compatibility matrix for fallback models. Validate structured outputs against a schema, and do not assume that a syntactically valid answer is factually correct.
5. Make confidence and provenance part of the response
AI applications often collapse several different states into one answer: the system found no evidence, retrieval failed, the model was uncertain, or the provider was unavailable. These states should not look identical to users or downstream services.
Represent them explicitly in the application contract. For example, return a status such as answered, partial, needs_review or unavailable, alongside source references and timestamps where relevant. Avoid treating a model’s self-reported confidence as a calibrated probability; use task-specific evaluations and observable evidence to decide when an answer can be shown.
For retrieval-based answers, preserve document identifiers, versions and retrieval timestamps. For tool actions, record the requested operation, authorization decision, result and any reconciliation status.
6. Design a degradation ladder
A practical system can define an ordered set of behaviors rather than improvising during an incident.
- Normal: full retrieval, model response, validation and citations.
- Reduced: skip an optional reranking or enrichment step while retaining core checks.
- Fallback: use a compatible alternate provider or a deterministic response path.
- Read-only: show verified information but disable state-changing actions.
- Safe stop: explain what is unavailable and provide a recovery path.
The ladder is task-specific. A customer-support summary may tolerate a reduced mode; a workflow that changes production infrastructure may need to stop whenever authorization, policy evaluation or target-state verification is unavailable.
7. Measure successful outcomes, not just uptime
A model endpoint can report high availability while the user-facing feature is failing because retrieval, parsing or tool execution is broken. Monitor the full workflow.
- End-to-end success rate and latency percentiles.
- Timeouts, rate limits, retries and circuit-breaker activations by dependency.
- Fallback frequency and success rate.
- Schema-validation failures, missing citations and retrieval freshness.
- Cost per successful task, including failed attempts and retries.
- Human escalation, correction and reversal rates where applicable.
Use traces to connect a user request to retrieval, model calls and tool execution. Redact sensitive data, control access to logs, and define retention policies. Observability should help teams diagnose failures without creating a second source of data exposure.
8. Test failure paths deliberately
Do not wait for a provider incident to discover your fallback is broken. Run fault-injection tests in a controlled environment: force a model timeout, return malformed JSON, make retrieval unavailable, simulate rate limiting, and drop a tool response after the action may have completed.
For each scenario, specify the expected user-visible behavior, whether the operation can be retried, what gets logged, and how the system recovers. Re-run these tests when changing models, prompts, retrieval pipelines or orchestration logic.
A practical architecture checklist
- Every external dependency has a timeout and a documented failure mode.
- Retries are bounded, and state-changing operations are idempotent or reconciled.
- Fallback models and deterministic paths are tested against task-specific quality thresholds.
- Security, authorization and policy checks cannot be bypassed by a fallback.
- Responses distinguish verified answers, partial results and unavailable capabilities.
- Logs and traces include useful metadata without exposing secrets or unnecessary personal data.
- Failure scenarios are included in release tests and operational runbooks.
Conclusion: reliability is an architectural property
Reliable AI is not achieved by selecting a single powerful model and hoping it stays available. It comes from designing the surrounding system to expect partial failure and respond predictably.
Start with one user journey. Map every dependency, define what the user should see when each dependency fails, and test those paths. Then expand the pattern across the product. The result is an AI application that may occasionally offer less functionality—but is far less likely to become misleading, unsafe or completely unusable.
For a related perspective, read Future Tech Diaries’ guides on the engineering control plane for AI agents and why network boundaries matter for agent security.
Comments
0To comment, choose whether you want to register or continue as a guest.